Which AI labs publish an RSS feed, and which make you scrape
We checked all of them the boring way, by asking for the feed and seeing what came back.
To keep up with the labs we fetch twenty-three sources every fifteen minutes. Setting that up meant asking every lab for a feed and writing down what came back. Here's the list, since it's useful if you want to follow this stuff yourself.
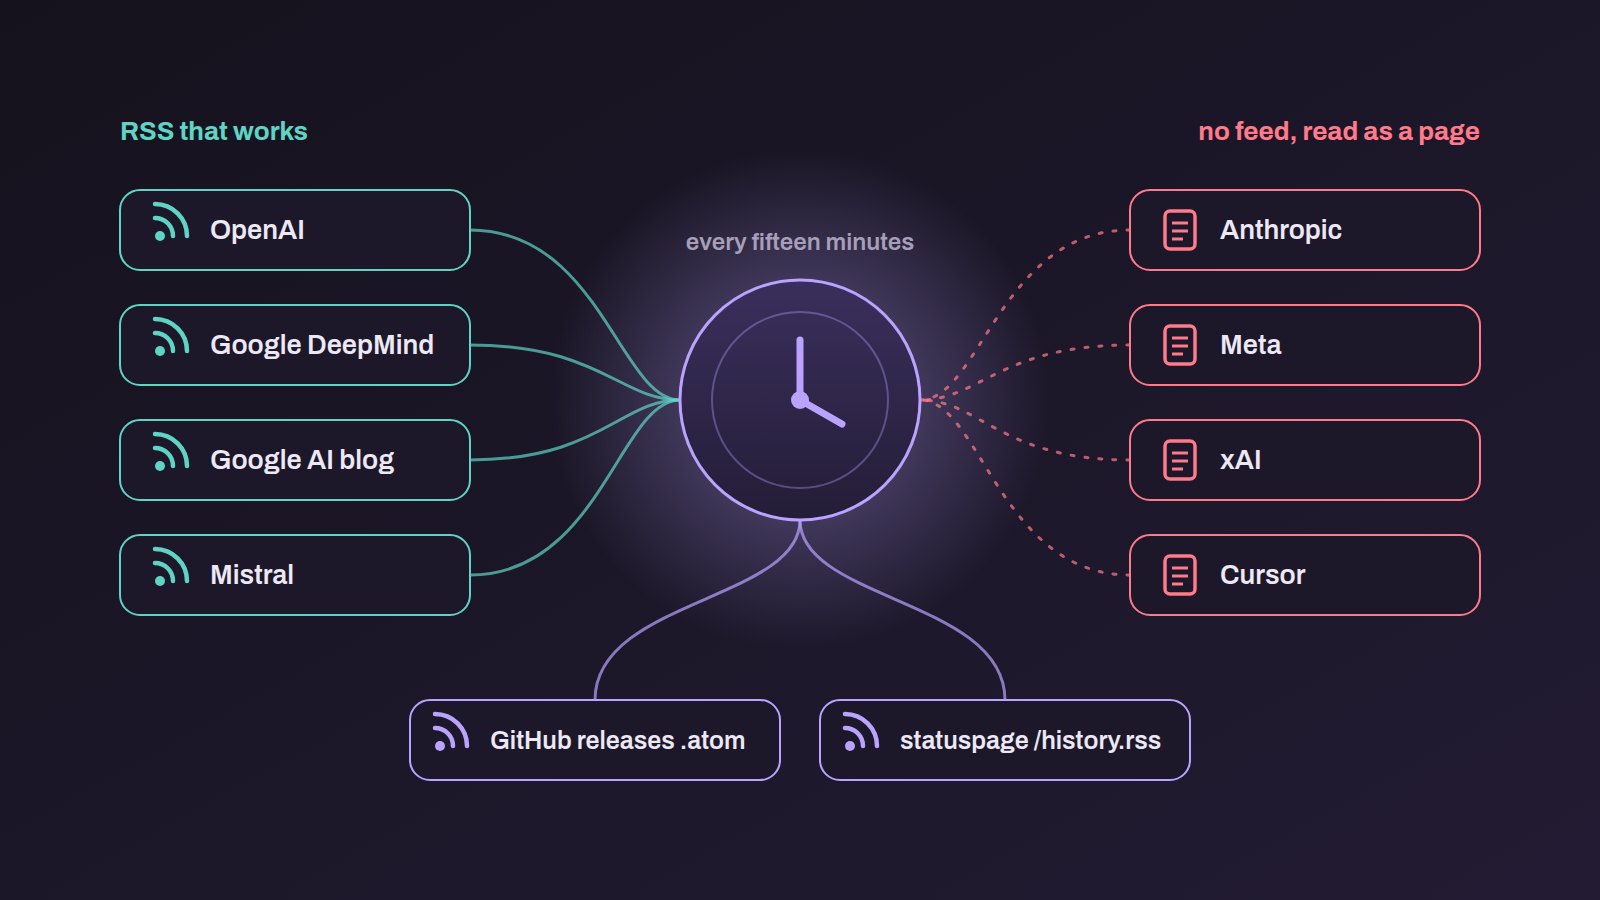
They have a feed and it works
OpenAI publishes at openai.com/news/rss.xml. It's a big one (well over a thousand items), and the old /blog/rss.xml redirects to it.
Google DeepMind has deepmind.google/blog/rss.xml. It's clean RSS with one catch: the description field is empty on every item, so you get a headline and a link and that's it.
Google's own AI blog is at blog.google/innovation-and-ai/technology/ai/rss/. The path you'd guess redirects there.
Mistral has mistral.ai/news/rss. It's valid RSS served with the wrong content type, so some readers refuse it. Weirdly, the feed itself is fine. It just says plain text on the label.
They don't, and it's not close
Anthropic has no feed. There's nothing at /rss.xml and nothing linked in the page head, and we couldn't find one anywhere else either. The posts are in the page, buried in the data the site ships to build itself, so that's where we read them from.
Meta has no feed either, at any of the four paths worth trying. Its AI blog also does something odd. Ask for the page as a browser and you get an error shell with no posts in it; ask as anything else and the posts are right there in the HTML. We read it the second way (I'm still not sure why it works like that).
xAI and Cursor both publish changelogs and news as ordinary web pages with no feed attached, so both get read as pages.
The bits everyone gets right
GitHub gives every repo a releases feed if you add .atom to the releases URL. That covers Claude Code and Codex, plus the official Python libraries, and it's the most reliable thing on the whole list.
Status pages are the other easy one. Both OpenAI and Anthropic run on statuspage.io, and every statuspage site has a /history.rss. Add one to a feed reader and an outage reaches you without anyone checking the page.
Deprecation pages are the hard case
Nobody publishes a feed of models being retired, which is a shame, because it's the announcement most likely to break something you built. OpenAI and Anthropic both keep that on a normal documentation page.
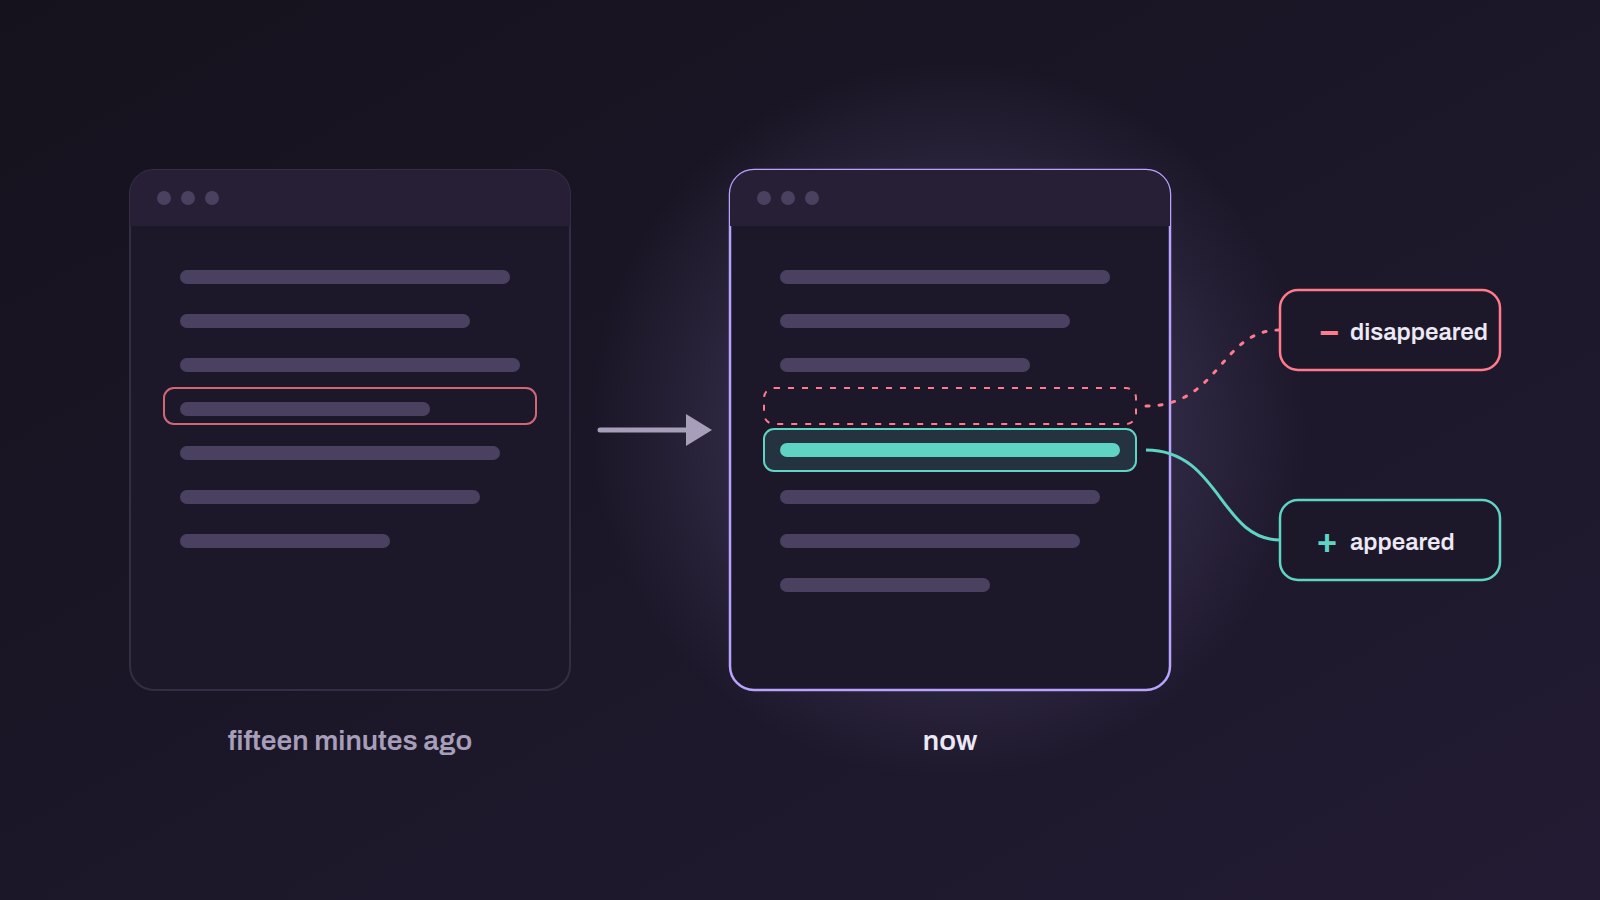
So we take a copy of the page every fifteen minutes and compare it with the last one. When a line appears or disappears, that's the item. It's crude, granted. It catches copy edits as well as real changes, so a changed line tells you where to look and leaves the meaning to you.
What this means if you just want to keep up
Four working feeds, from three companies, and you can follow those in any reader today. The rest you can't, unless someone else does the scraping. That scraping is where a lot of our news starts.
Every claim above was checked by fetching the URL, including the ones that 404ed. If a lab quietly ships a feed later, we'll notice, because we're still asking.